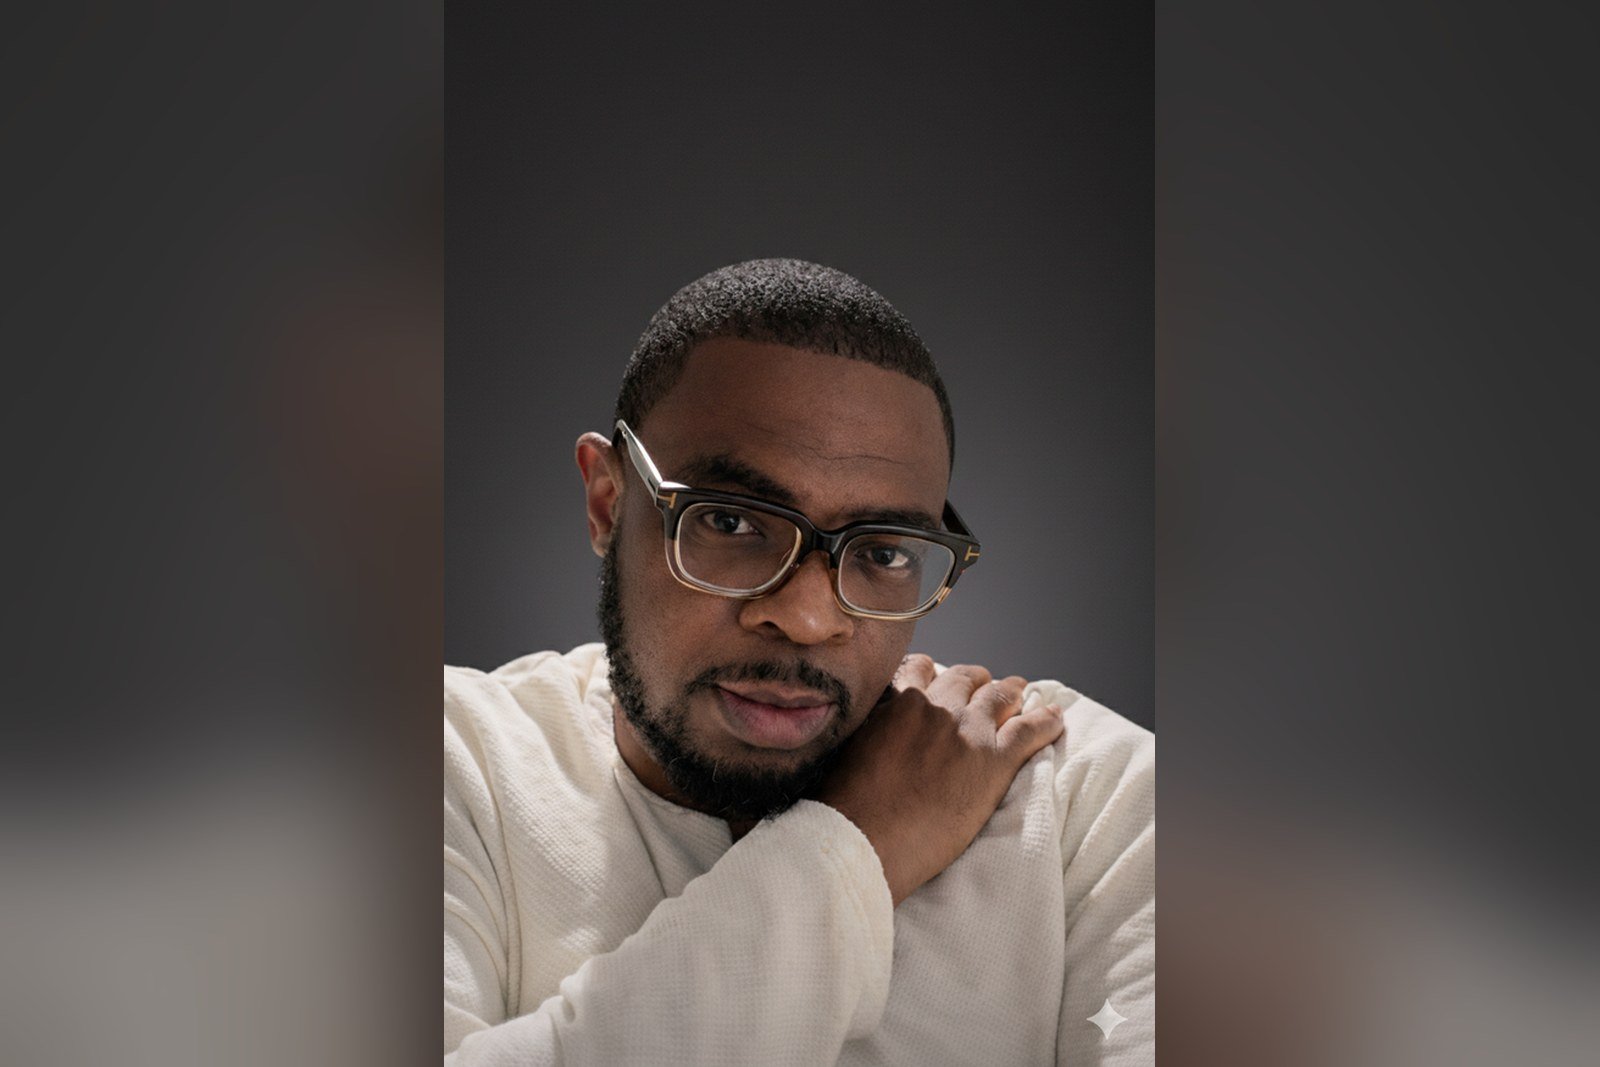
Ahmed Oladapo, also known as Dataguy, is an experienced data engineer with over eight years of designing and building scalable data solutions. He holds an MSc in Data Engineering and AI from Data ScienceTech Institute, where he developed advanced expertise in data science, machine learning and artificial intelligence.
He has collaborated extensively with cross-functional teams, including data scientists, business analysts and IT professionals, and has a track record of delivering robust data pipelines, automating data processes, and optimising data storage and retrieval to support effective data-driven decision-making.
What sparked my interest in data engineering?
I was drawn to data engineering when I realised that meaningful insights are only as strong as the infrastructure that supports them. I was initially a data analyst, but I repeatedly encountered inconsistent and unreliable data. At first, I assumed this was specific to the companies I worked with, but over time I realised it was a systemic challenge across organisations. That realisation sparked my desire to tackle the problem at its source, and now, close to a decade later, I can confidently say:
Meaningful insights are only as strong as the infrastructure that supports them.
The principles behind reliable pipelines
As a data engineer, when designing scalable and reliable data pipelines, I am guided by a few core principles:
- Simplicity
- Observability
- Ownership
Pipelines should be easy to understand, resilient to failures, and straightforward to debug. I focus on building systems that recover gracefully, produce consistent results, and make potential issues visible early. Above all, I believe every pipeline should have clear ownership, because reliability improves dramatically when someone is accountable for both the data and its impact.
What keeps me ahead?
I’m intentional about investing my time and resources in continuous growth, because in a fast-moving field like data and AI, learning isn’t optional.
Growth is a responsibility, not a choice.
And no one grows efficiently in isolation, which is why I’m intentional about collaboration, community engagement, and attending conferences that offer real-world perspectives. Staying connected to industry trends helps me remain relevant and effective.
What guides my technology choices when building data solutions?
Several tools and technologies have shaped the way I work, but the greatest impact has come from those that promote strong engineering discipline. Modern data warehouses, analytics engineering frameworks and orchestration tools have helped standardise testing, documentation and collaboration around data.
More than any single tool, what matters most to me is choosing technologies that reduce complexity, simplify system maintenance, and enable teams to focus on delivering value rather than constantly troubleshooting broken pipelines.
What are the most common mistakes organisations make with their data?
A common mistake organisations make is prioritising speed over sustainability. Pipelines are often built to answer immediate questions, but without clear ownership or shared definitions, this approach gradually erodes trust in the data. Treating data as a product, with standards, accountability and alignment to business needs, prevents these issues and enables data to scale reliably alongside the organisation.
My mentorship philosophy
My mentoring philosophy is all about fundamentals and curiosity. I often tell mentees:
There is the radio, and there is what’s making noise inside the radio. While everyone focuses on the radio, those who become great focus on understanding the noise.